Project Page
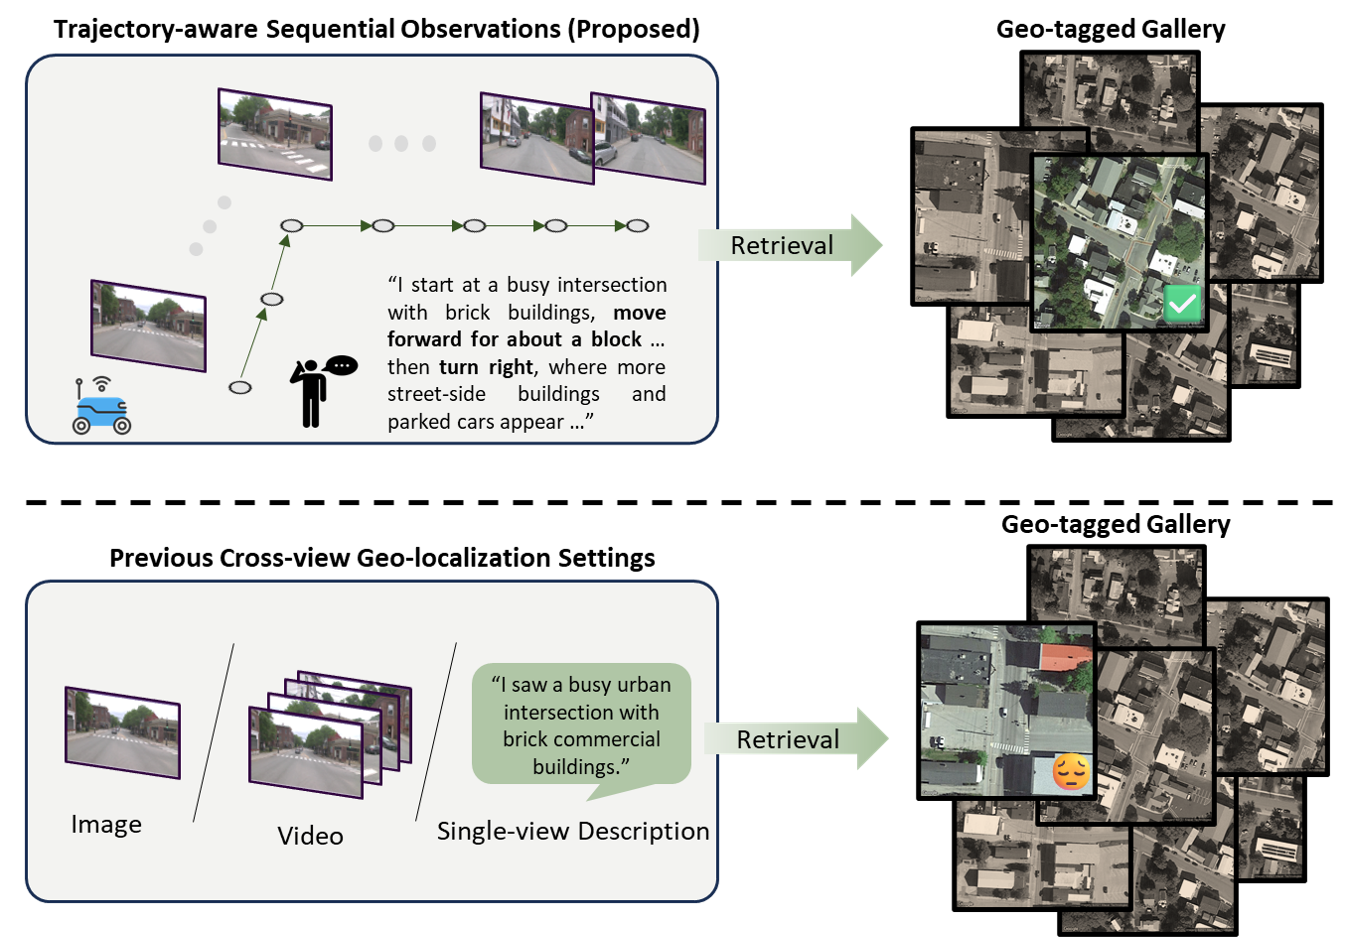
We build SeqGeo-VL, ~39K paired videos, trajectories, route descriptions, and overhead images, and train TrajLoc, a VLM embedding model for cross-view matching with overhead maps.
I am a second-year CS PhD student in the Multimodal Vision Research Laboratory at Washington University, advised by Dr. Nathan Jacobs. I study how vision-centric agents solve tasks across different embodiments (e.g., wheeled robots, humanoids, and aerial robots), and how world modeling and unified multimodal modeling can improve them.
Before joining WashU, I obtained my Bachelor's and Master's degree from Wuhan University. I also spent a wonderful time at Microsoft Research Asia in 2024, working on MLLMs for scientific diagrams.
I work on embodied agents, spanning multimodal learning, spatial reasoning, and world models, with a focus on embodied perception and reasoning. If you share similar interests, feel free to reach out for chatting!
My past research applied AI to domains including games (collaboration with Tencent LightSpeed Studios), agriculture (with Microsoft AI for Good), geoscience (with Microsoft Research), and transportation (through the NVIDIA AI City Challenge), where I believe domain-grounded problems can motivate, shape, and co-evolve with methodology.
We build SeqGeo-VL, ~39K paired videos, trajectories, route descriptions, and overhead images, and train TrajLoc, a VLM embedding model for cross-view matching with overhead maps.
Two research projects explore unified world modeling and VLM policy learning / representation learning for world models.
Designed the first benchmark for evaluating MLLMs on geologic map interpretation. Proposed an agentic baseline with expert tool integration achieving state-of-the-art performance.
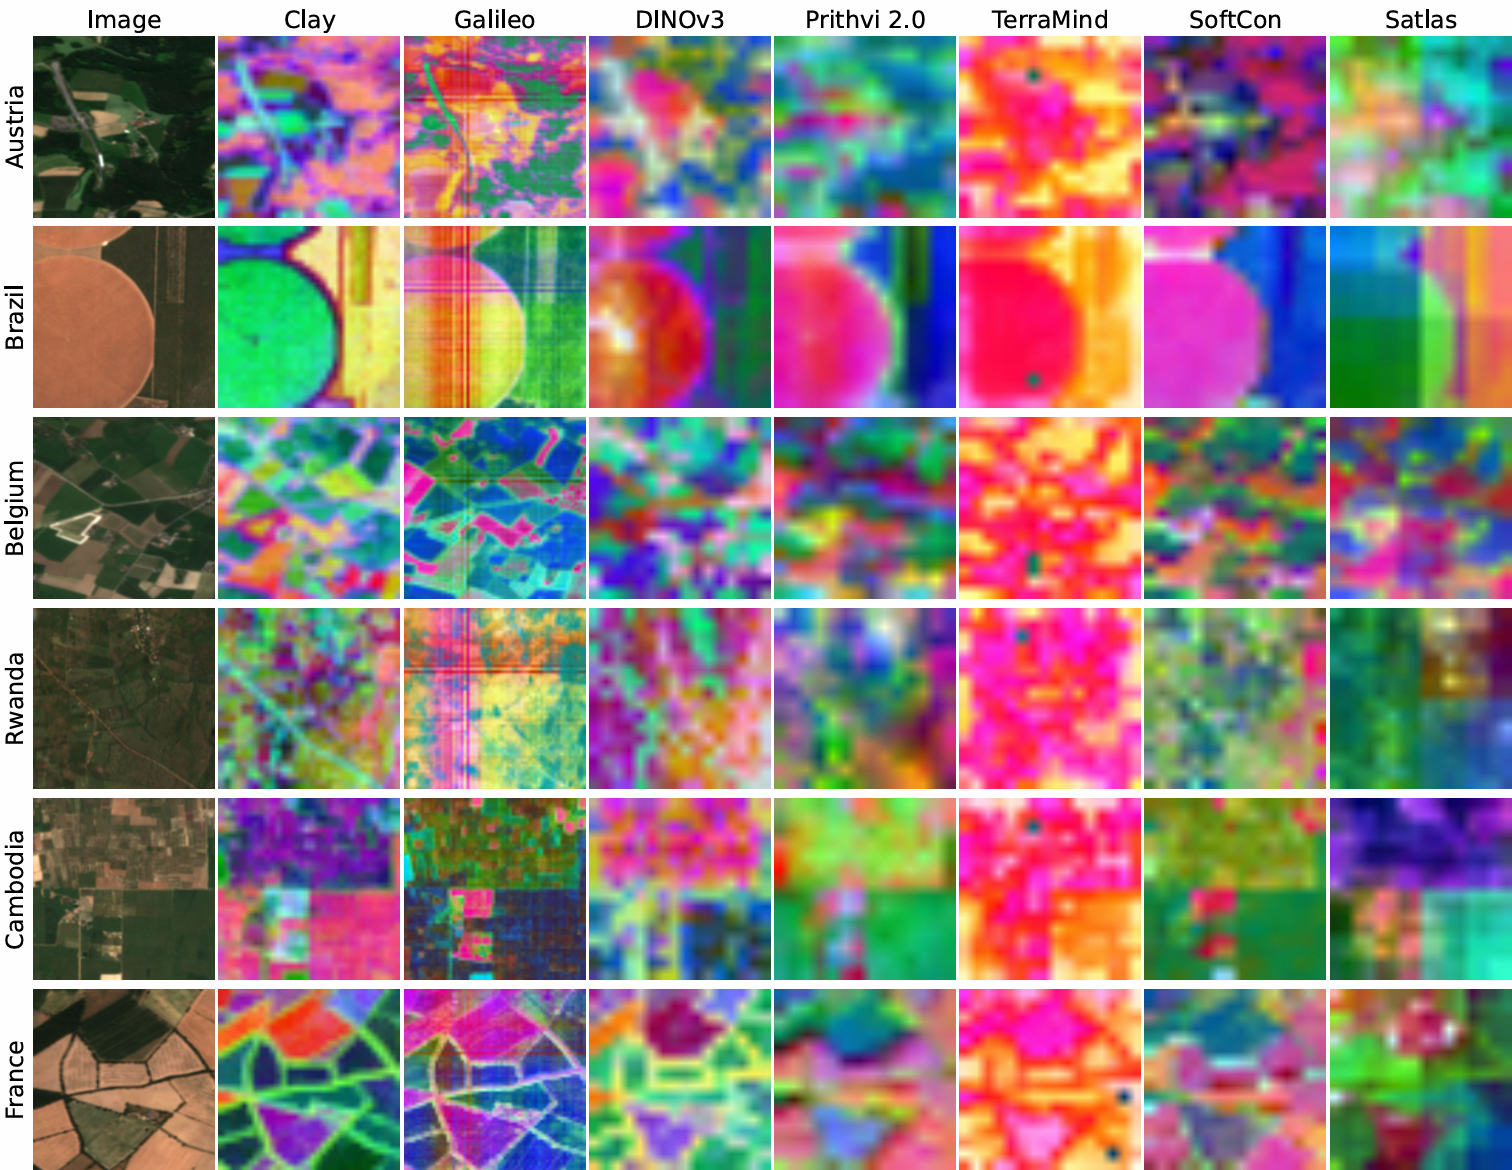
This work explores Earth embedding distillation.
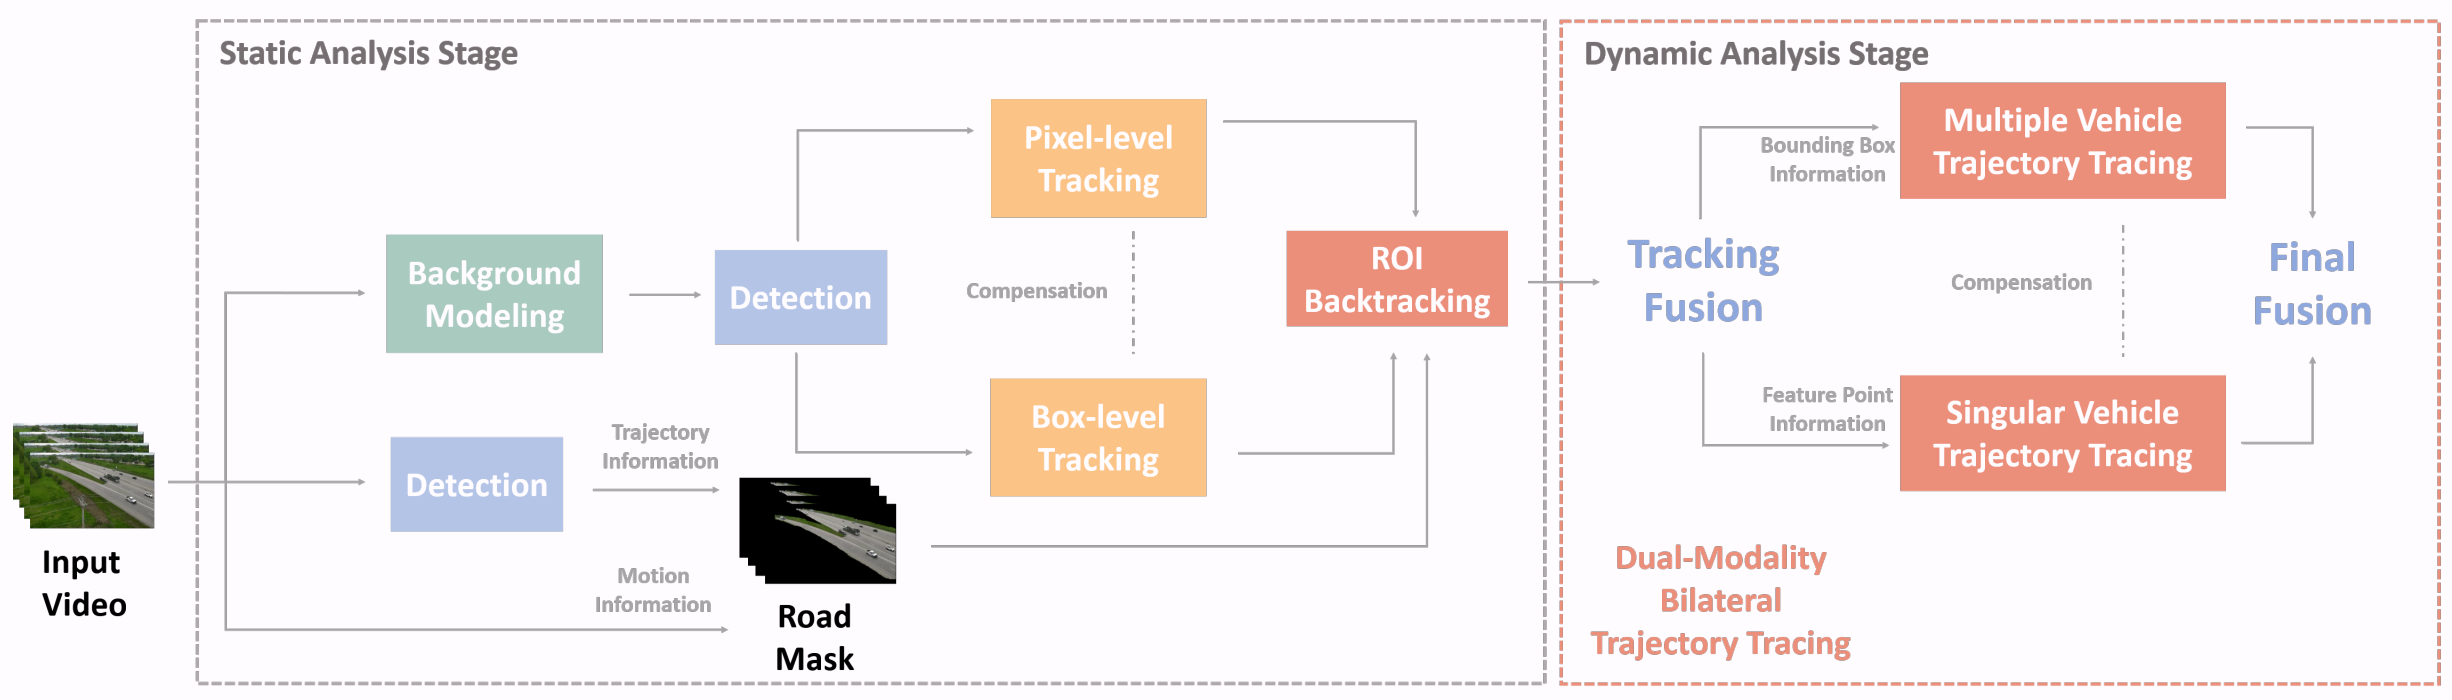
Developed with industry collaborators Microsoft AI for Good Lab and Wherobots. A scalable model recipe and data pipeline for planetary-scale field delineation.